What do AI security agents find that SAST does not, and what do they miss that SAST catches?
An attacker-reachable recall study of deterministic SAST and AI security agents
We ran nine productized security configurations once each, blind, on 20 open-source web applications. For the seven endpoint-aware configurations, a finding counts only when it locates the attacker-controlled source and the dangerous sink of a curated vulnerability, each within two lines; DeepSec is scored separately.
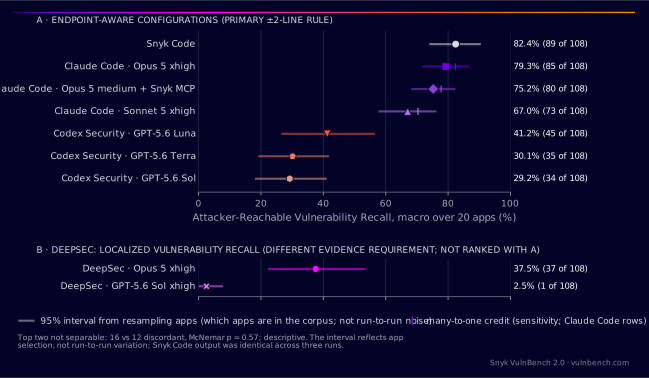
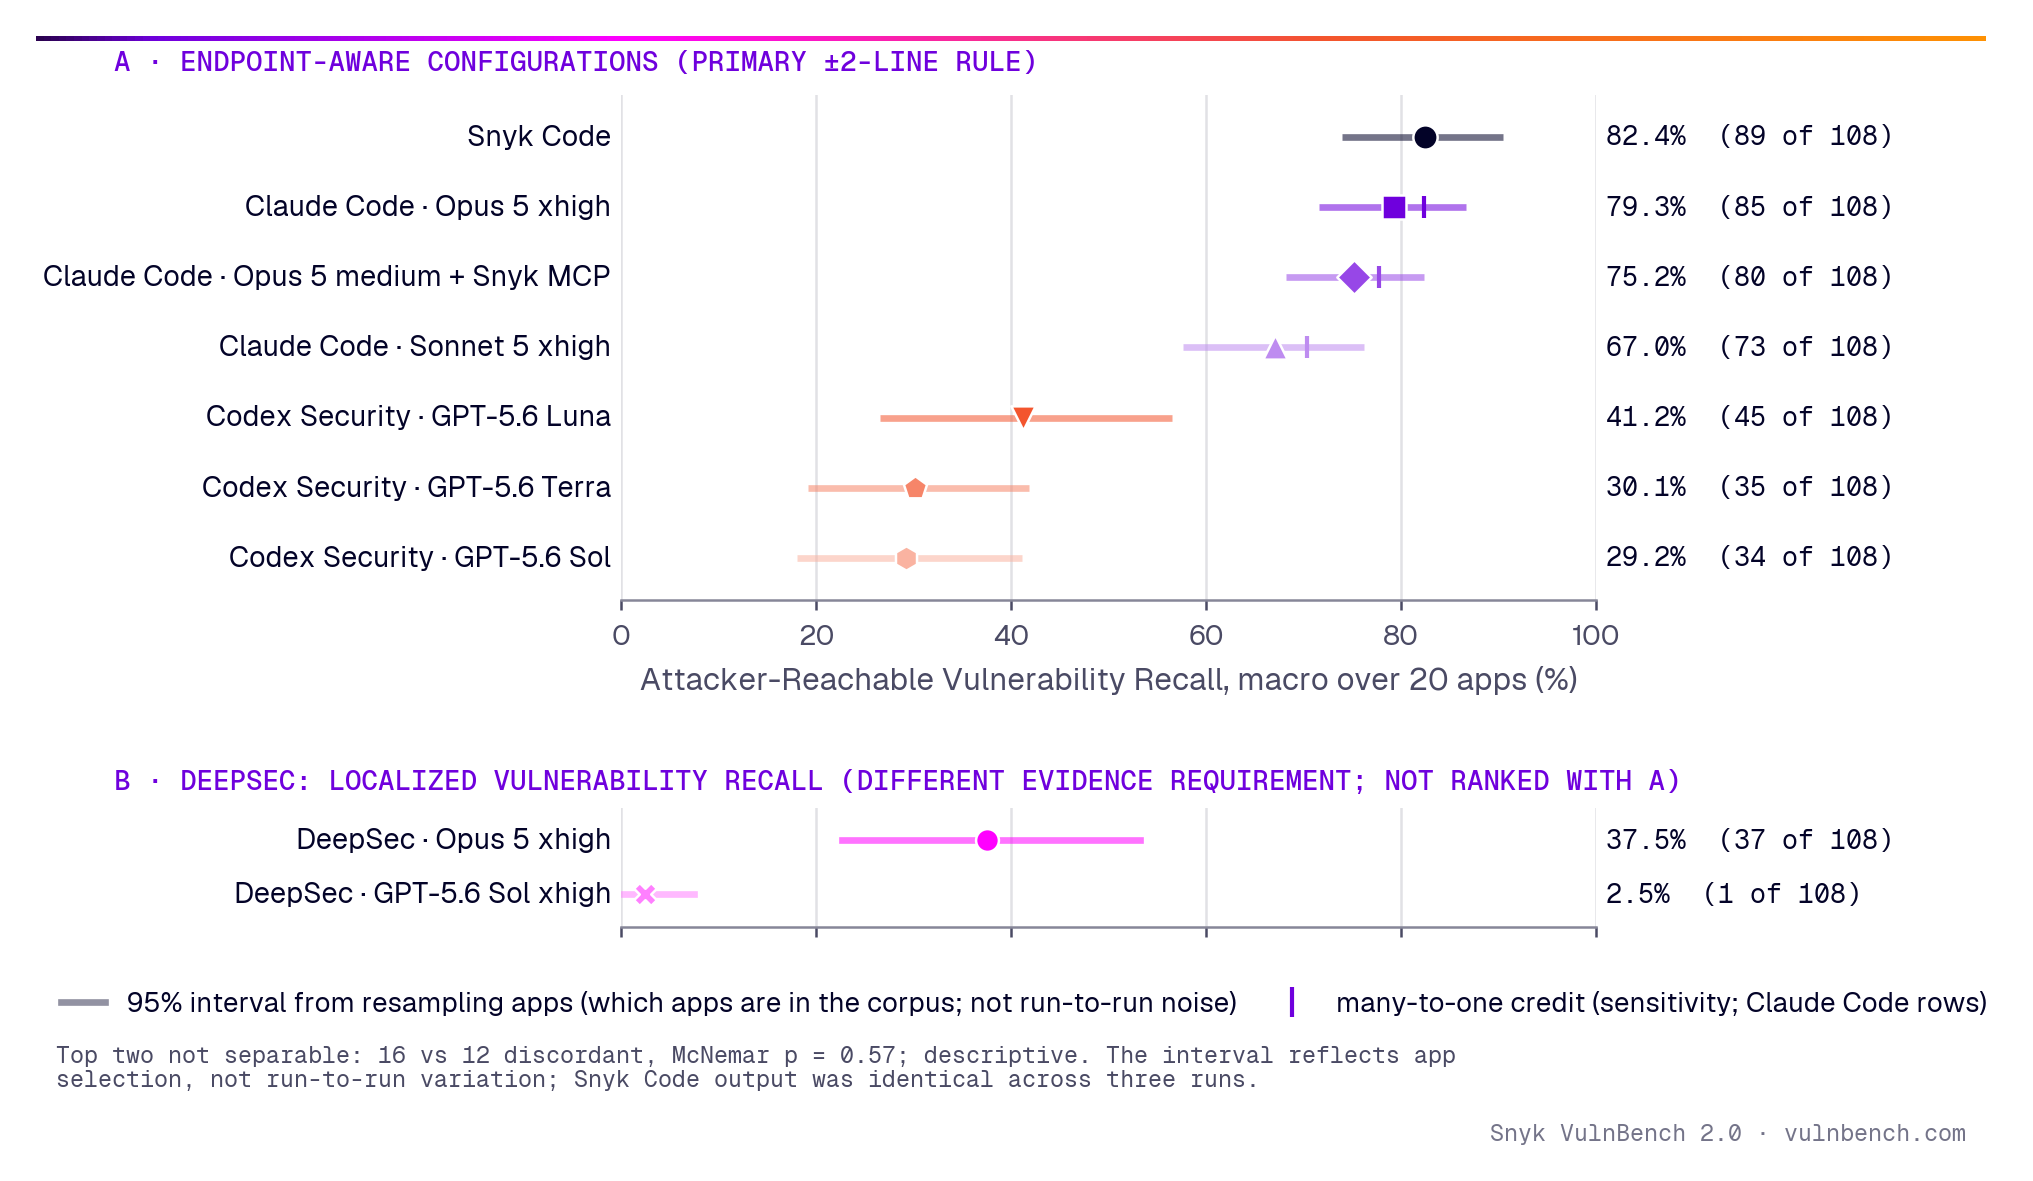
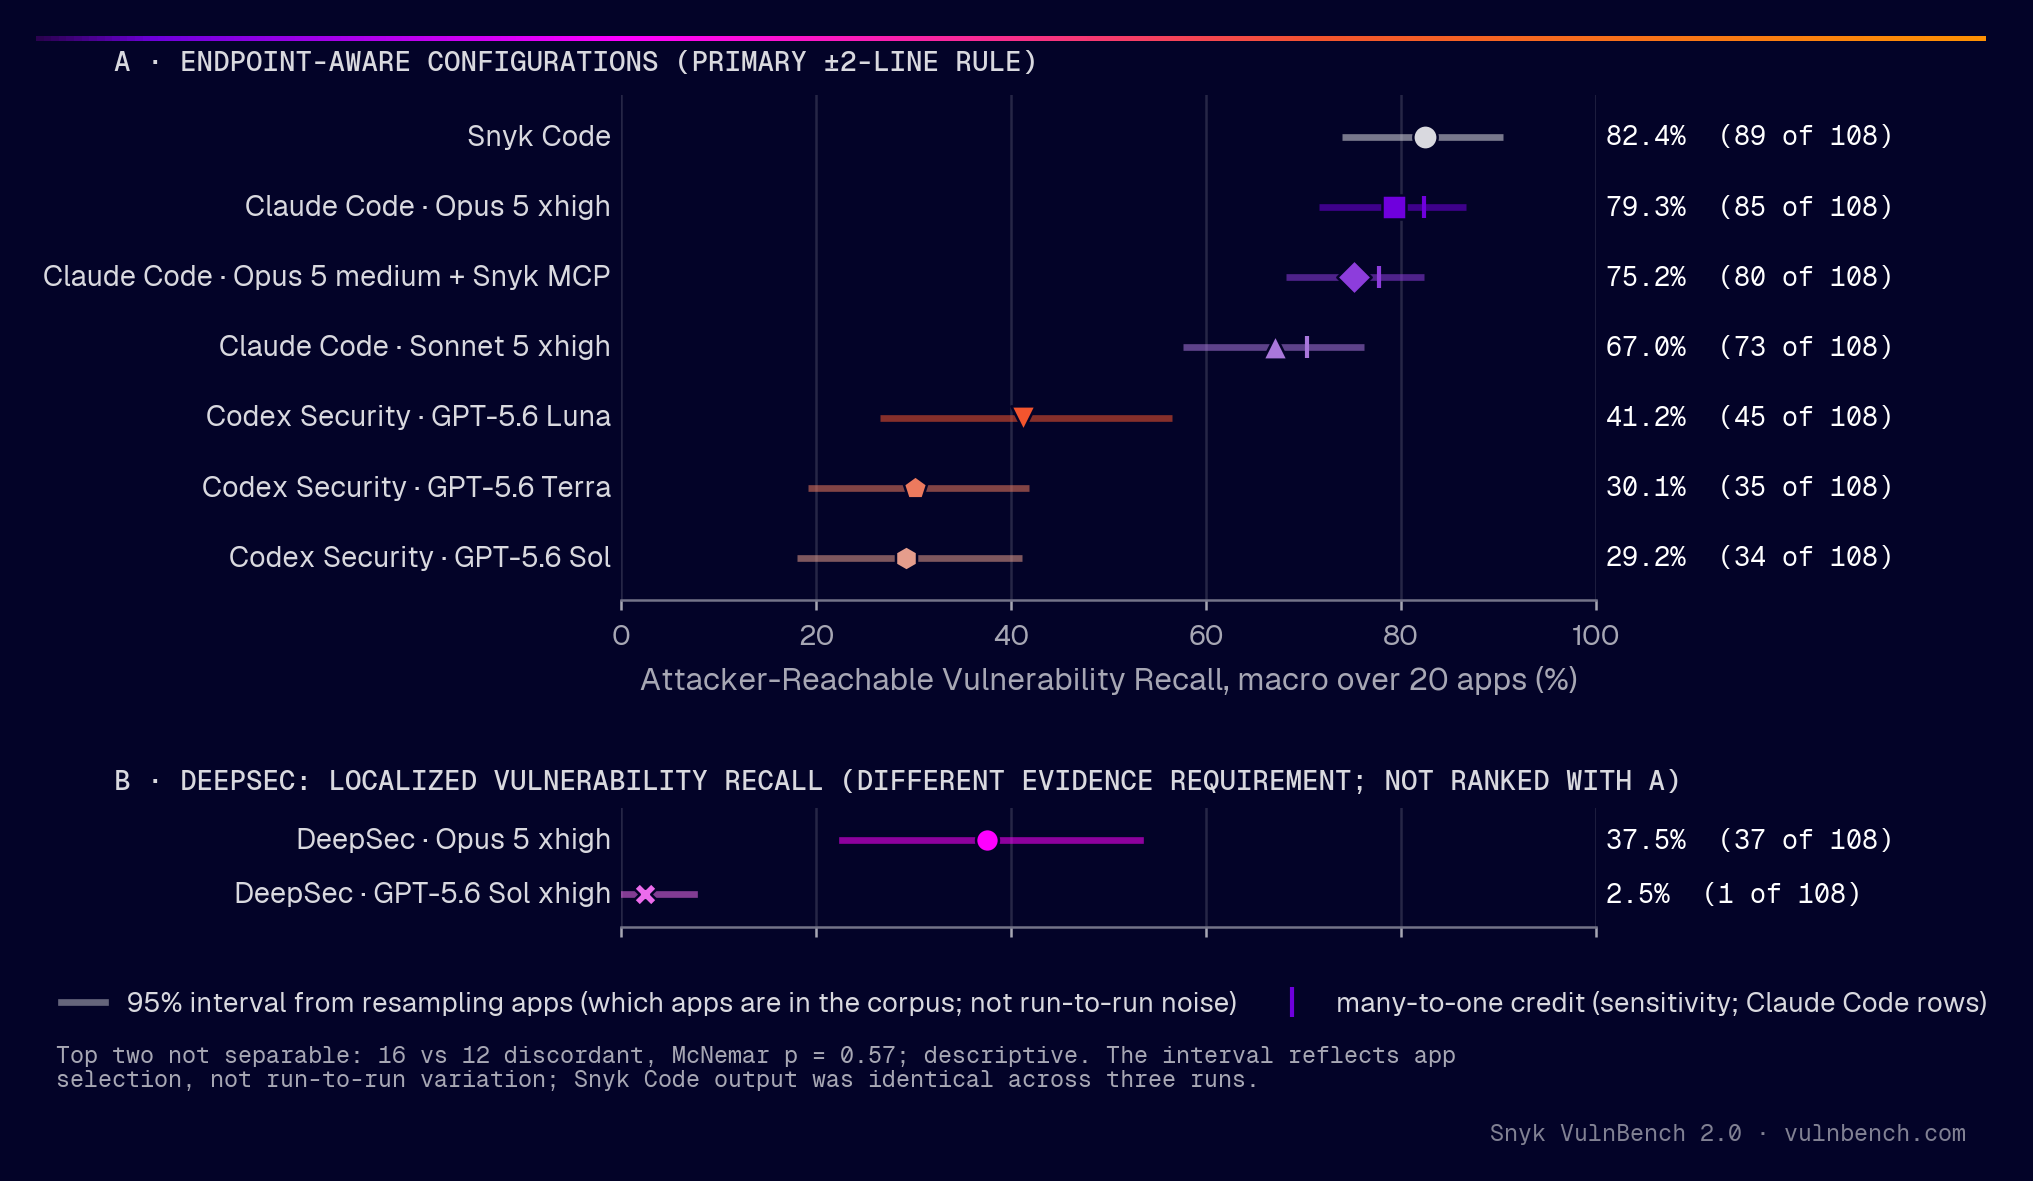
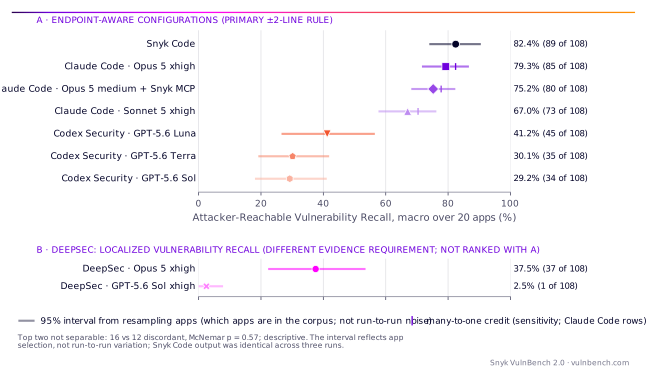
Figure 1.Main recall results. (A) The seven endpoint-aware configurations: macro Attacker-Reachable Vulnerability Recall with the matched count; the bar is a 95% interval from resampling the 20 applications, which shows how much a score depends on which applications are in the corpus, not run-to-run variation. (B) DeepSec, scored with localized recall, on its own axis. The tick on the Claude Code rows marks the score under many-to-one credit, a sensitivity check. The top two cannot be separated: they disagree on 28 vulnerabilities, 16 vs 12 (McNemar p = 0.57, descriptive).PNG, lightPNG, darkSVG, lightSVG, dark
Snyk Code 82.4% (89 of 108) and Claude Code /security-review with Opus 5 xhigh 79.3% (85 of 108): they disagree on 28 vulnerabilities, 16 to 12, too few to tell them apart.
Together they match 101 of 108, the same as all seven endpoint-aware configurations combined: a ceiling across configurations, not one tool's result.
DeepSec is scored with localized recall, a different evidence requirement, and is shown separately.
In this study neither engine was sufficient alone. A vulnerability class an engine does not report is a real miss here, because every reference vulnerability is attacker-reachable.
Dataset 2.0.0 · Snyk VulnBench 2.0 · 108 reference vulnerabilities · one run per configuration and application · Source: published 2.0 paper
DeepSec · localized recall, a different evidence requirement
Configuration
Localized recall (macro, matched)
95% interval
Precision against the reference set (lower bound)
DeepSec · Opus 5 xhigh
37.5% (37 of 108)
22.6–53.2%
7.1%
DeepSec · GPT-5.6 Sol xhigh
2.5% (1 of 108)
0.0–7.5%
10.0%
What the results mean in practice
An AI security engine is a model inside a harness.
Deterministic SAST and AI review covered different ground; what an AI engine reported depended on its harness as much as on its model; and coverage and cost were only loosely related.
01
SAST and AI review cover different ground
Snyk Code matched 82.4% (89 of 108) and Claude Code /security-review with Opus 5 xhigh 79.3% (85 of 108). They disagree on 28 vulnerabilities, 16 matched only by Snyk Code and 12 only by Opus 5 xhigh; a corpus of this size cannot separate them.
Interpret with care: A union across configurations is a ceiling, not one tool's result. Combining the two also combines their queues: 539 findings for 101 matches.
Claude Code's /security-review excludes ReDoS and reports prototype pollution and open redirect only at extremely high confidence. On the 20 reference vulnerabilities in those classes, Snyk Code matched 18 and Opus 5 xhigh 9; on the 81 others (excluding 7 cross-site scripting vulnerabilities in React and Angular applications), Opus 5 xhigh matched 71 and Snyk Code 67.
Interpret with care: The policy reading rests on the policy text and one supplementary control run; harness and model cannot be fully separated by this design.
Snyk Code scanned all 20 applications in 8 minutes; the comparable AI configurations took between 2.4 hours and 8.9 hours.
Interpret with care: One run per configuration and application: every ratio is a single observation. Snyk Code has no per-scan model cost; its license cost is outside this study.
Snyk Code and Opus 5 xhigh are the two highest-ranked endpoint-aware configurations under every one of the 20 alternative scoring rules; Snyk Code ranks first under 18 and Opus 5 xhigh under the other two; their order should not be read as a result.
Interpret with care: Rescoring shows which conclusions survive changes in the scoring rule; it does not add statistical power.
Releases measure different things. JS 1.0 measured repeatability and agreement with Snyk Code; 2.0 measures attacker-reachable recall against an independent reference set.
The paper, reviewed methodology, source snapshot, and release data use stable public links.
Preferred citation
Snyk VulnBench 2.0
@misc{tal2026snykvulnbench20,
  author = {Tal, Liran and Liu, Chris and Fereday, Charlotte and Roth, Sebastian and Clark, Brian},
  title = {How Deterministic SAST and AI Security Agents Divide the Work: Coverage, Harness Policy and Cost in Snyk VulnBench 2.0},
  year = {2026},
  eprint = {2610.38617},
  archivePrefix = {arXiv},
  primaryClass = {cs.CR},
  doi = {10.48550/arXiv.2610.38617},
  url = {https://arxiv.org/abs/2610.38617}
}
Liran Tal · Chris Liu · Charlotte Fereday · Sebastian Roth · Brian Clark
Snyk VulnBench JS 1.0
@misc{tal2026snykvulnbenchjs10,
  author = {Tal, Liran and Kloos, Johannes and Rudich, Arsenii and Thoemmes, Stephen and Nair, Manoj},
  title = {Snyk VulnBench JS 1.0: Can LLMs Find the Same Bugs Twice?},
  year = {2026},
  url = {https://arxiv.org/abs/2606.15762}
}
Liran Tal · Johannes Kloos · Arsenii Rudich · Stephen Thoemmes · Manoj Nair